
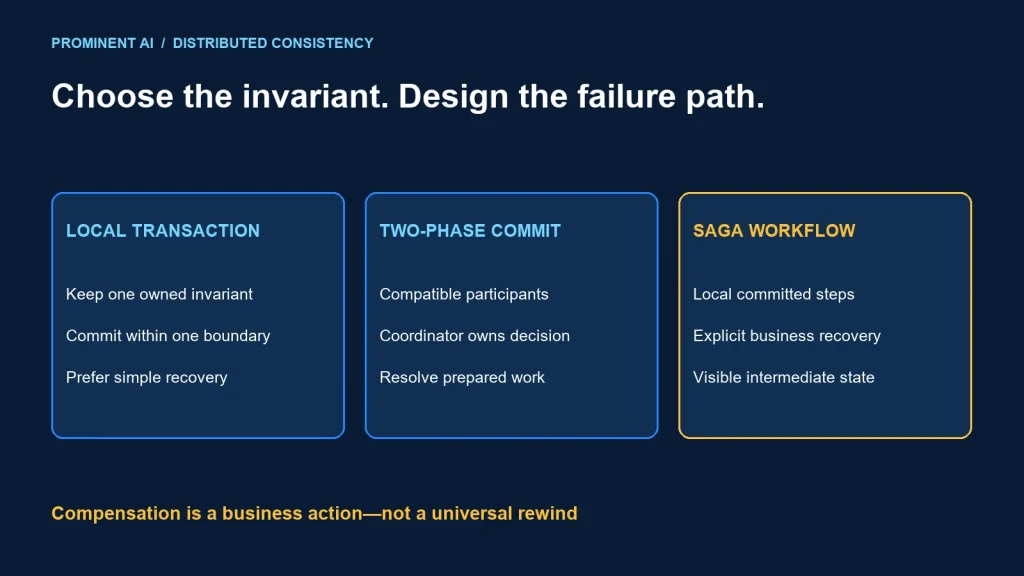
A Saga coordinates a business workflow through local transactions and explicit recovery or compensation. Two-phase commit coordinates an atomic commit decision across compatible transactional participants. Choose according to the invariant, participant capabilities and acceptable failure behavior. A Saga does not reproduce database isolation across services, and an arbitrary external API cannot be included in 2PC merely by calling it from a transaction.
Key takeaways
- First ask whether the invariant belongs inside one local transaction.
- Compensation is a business action, not a universal rewind.
- Both forward and recovery steps need durable progress and duplicate handling.
- Long-running workflows need visible intermediate states and an operational owner.
Saga vs two-phase commit
Begin with a precise rule: what must never become true, what can be temporarily incomplete, and how long can that state remain? “Keep everything consistent” is too vague to choose a transaction design.
AWS’s Saga guidance describes coordinating transactions across services and the complexity of recovery. A Saga can support long-running business work, but developers must define what each completed step means and how the process reaches an acceptable outcome after failure.
PostgreSQL’s prepared-transaction documentation illustrates the prepare/commit mechanism for an external transaction manager. Prepared transactions retain locks and require prompt resolution. This is not a recommendation to leave transactions prepared while waiting for a user or unrelated SaaS response.
| Dimension | Saga | Two-phase commit |
|---|---|---|
| Unit of work | Sequence of committed local operations | Coordinated transaction across compatible resources |
| Failure response | Retry, compensate or resolve through business recovery | Resolve prepared participants using the transaction decision |
| Intermediate state | Visible and must be modeled | Governed by resource transaction and isolation behavior |
| Participant requirement | Business APIs with suitable operation contracts | Resources supporting the chosen transaction protocol |
| Operational concern | Stuck workflows and failed compensation | In-doubt transactions, locks and coordinator recovery |
Neither option is a shortcut around domain design. If inventory allocation and order acceptance require an immediate indivisible rule, consider whether separating them into independently owned services is the right boundary. A modular application with one local database transaction may be simpler.
Two architecture diagrams
Saga with explicit workflow state
Client → durable workflow record
          ↓
      reserve stock → authorize payment → confirm order
          │                  │                  │
      local commit       provider outcome    local commit
          └──────── progress, operation IDs and timeouts ────────┘
Failure path: reconcile unknown result → retry or compensate
Unresolved compensation → owned review queue, never silent success
This fictional order example uses a payment authorization, not a claim that every provider supports the same reversal contract. If confirmation fails, the system must determine whether the authorization exists before deciding to void it. A timeout alone cannot answer that question.
Compatible resources under a transaction coordinator
Transaction coordinator
     ├─ phase 1: ask participant A and B to prepare
     ├─ participants persist their votes/state
     └─ phase 2: communicate the durable commit or rollback decision

Coordinator recovery must resolve participants left in doubt.
Only resources supporting the transaction contract participate.
This sketch omits product-specific recovery and isolation details. Do not hand-build a distributed transaction manager from this diagram. Verify database, driver, platform and coordinator support together, including restart behavior and administrative recovery.
Compensation is a business decision
Microsoft’s compensating-transaction guidance explains why compensation may not restore the original state and can itself fail. Record recovery information and make repeated compensation safe. The correct order depends on business constraints, not an automatic reversal of every line of code.
For the fictional order, releasing a stock reservation may be straightforward while undoing shipment after handoff is not. Identify the point after which the business needs a return, refund or manual exception rather than a technical cancellation.
| Forward action | Potential recovery | Question to settle |
|---|---|---|
| Reserve stock | Release the specific reservation | Has it expired or already been consumed? |
| Authorize payment | Provider-supported void/reconciliation | Is the outcome known and reversal still available? |
| Confirm order | Controlled cancellation transition | Has fulfillment crossed an irreversible boundary? |
| Send notification | Send a corrective message if appropriate | Can the communication actually be withdrawn? |
Do not restore a stale database snapshot to undo one step when other users may have made legitimate changes. Recovery should refer to the exact reservation, authorization or business action it is compensating.
Give compensation a stable operation identity, bounded retries and observable state. If a reversal response is lost, the compensation itself may be uncertain. Repeating it safely requires its own contract, just like the original action.
Separate temporary technical failure from business rejection. A service outage may justify a retry; insufficient stock may require an alternative, cancellation or a customer decision. Do not apply one generic retry loop to all outcomes.
Choreography vs orchestration
With choreography, participants react to agreed events. With orchestration, an explicit workflow owner directs steps and records progress. Neither removes the need for meaningful events, stable contracts and durable recovery.
Choreography can fit a small number of independent reactions, but process ownership can become difficult to see as dependencies grow. Review the end-to-end event graph, not just each service’s handler. Avoid hidden loops where one recovery event restarts the original process.
Orchestration can make deadlines, branching and intervention visible in one workflow. The orchestrator still needs resilient storage and recovery, and must not become the location of every participant’s internal business rules.
Choose based on who can explain and operate the complete process. For a workflow spanning inventory, payment and fulfillment, the operations team should be able to identify the current step and next permitted action without querying several databases manually.
Version running workflows carefully. New code may encounter an instance created under an earlier contract. Store enough version information to resume or migrate it deliberately, and test deployments with in-flight work.
Workload selection matrix
| Workload | Candidate | Required evidence |
|---|---|---|
| Invariant inside one owned database | Local transaction | Correct boundary and isolation |
| Short operation across compatible transactional resources | Evaluate supported 2PC | Coordinator, failure recovery and lock impact |
| Long-running multi-service business process | Evaluate Saga | Intermediate states, compensation and ownership |
| Unrelated external API participates | Explicit workflow and reconciliation | Provider operation identity and recovery contract |
| No acceptable compensation for a critical invariant | Reconsider boundary or reserve before commitment | Business approval of the consistency model |
Do not compare only happy-path latency. Include recovery duration, oldest unfinished operation, operator effort, lock exposure, deployment independence and customer-visible status. State the acceptable uncertainty window before selecting technology.
Test partial failure before production
Use a bounded, non-production scenario with controlled participants. The following is a proposed test plan, not a claim of a deployed client system or measured result.
- Complete every step and verify the final business state.
- Reject stock reservation and confirm no payment action occurs.
- Lose the response after payment authorization; reconcile before repeating it.
- Crash the workflow owner after a participant commits but before progress is recorded.
- Deliver duplicate and out-of-order responses.
- Fail compensation and verify a visible, owned recovery state.
- Restart during recovery and resume without creating new business intent.
- Deploy a new workflow version while an older instance remains active.
For a 2PC candidate, separately test coordinator restart, a participant unavailable during decision delivery, unresolved prepared work and operator recovery. Use the product’s supported tools and runbook rather than guessing whether to force a commit.
Define what customers see during uncertainty. “Processing” with an operation reference may be more accurate than a generic failure that encourages duplicate submission. Ensure customer support can find the same operation without exposing sensitive payloads.
Monitor forward and recovery paths equally. A process that completes normal traffic quickly but leaves compensation stuck has not met its business objective. Set ownership and escalation for the oldest unresolved workflow, not merely the average duration.
See the idempotency guide for replay-safe actions and the modular-monolith comparison before introducing distributed boundaries.
Common questions
How does a Saga handle transactions across microservices?
It coordinates committed local operations and explicit recovery steps, using durable progress and business compensation where appropriate.
Is a Saga the same as distributed ACID rollback?
No. Other work may observe intermediate state, and compensation may not restore the original state exactly.
Can any external API join two-phase commit?
No. A participant must support the required transaction protocol and recovery contract. An ordinary HTTP request does not establish that support.
What happens if compensation fails?
Persist its progress, retry safely within policy and route unresolved work to an owned recovery process.
Should every microservice workflow use a Saga?
No. Consider a local transaction, simpler asynchronous reaction or a different service boundary before adding workflow coordination.
Choose a consistency model your teams can recover
Bring the business invariants, participant contracts and failure scenarios. Request an API integration architecture review to compare local transactions, distributed coordination and recovery workflows.