
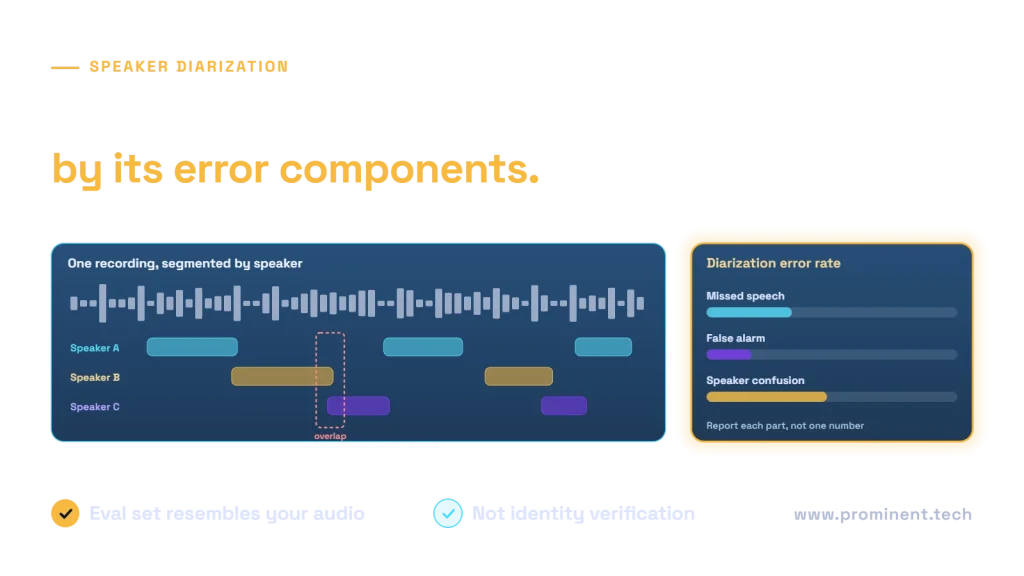
Speaker diarization determines who spoke when by assigning speaker labels to regions of audio. It does not, by itself, verify a person’s identity or establish their business role. Evaluate speaker attribution separately from transcription accuracy, particularly when people interrupt each other, share a channel or speak only briefly.
This guide explains common pipeline components, diarization error rate and production failure modes. Its timeline and arithmetic examples are fictional illustrations, not recorded calls or model benchmarks.
How a diarization pipeline works
Authorized audio
    → detect speech activity and changes
    → segment speech and represent speaker characteristics
    → group or model speaker activity over time
    → handle overlap and refine segment boundaries
    → align speaker labels with transcript words / phrases
    → review uncertain attribution and publish permitted output
This is a conceptual pipeline. Implementations differ: some combine several stages in neural models, while others use modular segmentation, embeddings and clustering. Do not assume a product exposes every intermediate stage or uses the same algorithm.
A speaker representation captures characteristics useful for grouping speech. The labels are usually session-relative identifiers. “Speaker 2” in one call should not automatically be treated as the same person as “Speaker 2” in another.
A fictional overlapping timeline
Time:        0s       2s       4s       6s
Speaker A:   [----------------]
Speaker B:                [----------------]
Overlap:                  [--]
During overlap, more than one speaker can be active. A system forced to choose a single label can miss part of the speech or attribute words incorrectly. The downstream interface should preserve what the selected output actually represents rather than pretending every moment has one certain speaker.
Diarization is different from recognition, separation and identification
| Task | Question answered | Not established |
|---|---|---|
| Speech recognition | What words were spoken? | Who said them |
| Diarization | Which apparent speaker was active when? | Verified real-world identity |
| Source separation | Can overlapping audio sources be separated? | Correct transcript or identity |
| Speaker identification | Does speech match a known speaker under a defined process? | Authority to perform a business action |
| Role mapping | Which participant is agent, customer or another role? | Reliable identity without supporting session evidence |
Azure’s diarization quickstart describes generic speaker identifiers in recognition output. Use trusted call-channel or session metadata for role mapping where available. Do not use diarization alone to approve an instruction or authenticate a caller.
Diarization error rate: separate its components
Diarization error rate, or DER, combines missed reference speech, false-alarm speech and speaker confusion relative to reference speaker time. The pyannote.metrics reference documents the metric and scoring options, including treatment of overlap and boundary collars.
DER = (missed speaker time + false-alarm speaker time
       + speaker-confusion time) / reference speaker time
Suppose a fictional evaluated region contains 100 reference speaker-seconds, with 5 missed, 2 false-alarm and 3 confusion speaker-seconds after the chosen alignment and scoring rules. The arithmetic DER is 10%. This is a declared example, not a measured model result.
Reference speaker time can count concurrent speakers during overlap; it is not always identical to recording duration. Use a recognized scoring implementation and state its settings rather than deriving a score by casually adding overlapping intervals.
| Error | Meaning | Production example |
|---|---|---|
| Missed speech | Reference speaker activity is not detected | A brief interruption or overlapping participant is omitted |
| False alarm | Activity is marked as speech where no reference speaker is active | Noise is labeled as a speaker turn |
| Confusion | Speech is assigned to the wrong matched speaker | One speaker is split or two are merged |
pyannoteAI’s benchmark explanation discusses these error categories. Do not compare headline DER values without checking dataset, overlap handling, scoring region, speaker mapping and boundary tolerance. A lower score under an easier protocol is not automatically a better deployment.
Word accuracy and speaker accuracy are separate
A transcript can recognize every word but assign a statement to the wrong participant. Conversely, speaker turns can be correct while important words are wrong. Evaluate critical entities, negation and attribution separately when summaries or action recommendations depend on who said what.
Overlap, short turns and unknown speaker counts
Overlapping speech is difficult because acoustic evidence contains multiple simultaneous sources. Detecting overlap, separating audio and correctly attributing recognized words are related but distinct tasks. Inspect the chosen model’s supported output rather than assuming it solves all three.
Short acknowledgments, laughter, changing microphones and similar voices can affect grouping. A transfer or supervisor joining a call can change the number of participants. Supplying a fixed speaker count may help only when that count is actually correct.
Streaming introduces another constraint: labels must be produced with limited future context. Some early assignments may be revised or uncertain. Define how the application handles changes and whether a post-call review produces a separate final artifact.
Build an evaluation set that resembles your audio
- Include relevant languages, accents and code switching.
- Cover call-channel quality, compression, noise and recording topology.
- Include overlap, interruptions, silence and short turns.
- Represent transfers, additional participants and long conversations.
- Use reviewed speech boundaries and speaker annotations.
- Record the scoring region, collar and overlap policy.
- Keep tuning recordings separate from held-out evaluation.
Use approved recordings or synthetic material with appropriate handling. Have reviewers resolve ambiguous annotations instead of pretending the reference is always obvious. Report sample counts and difficult slices alongside the aggregate.
Evaluate downstream use too. A summarizer may turn an attribution error into a claim that the customer accepted a proposal. Such a failure needs a review or approval boundary, not merely a better overall DER.
Production error taxonomy and response
| Symptom | Possible cause | Check before changing models |
|---|---|---|
| One person becomes several labels | Fragmented clustering, channel or voice changes | Segment length, audio topology and grouping settings |
| Two people share one label | Similar acoustics or incorrect speaker-count constraint | Reference annotation and participant changes |
| Interruptions disappear | Overlap or short-turn handling | Overlap scoring and model output limitations |
| Labels shift during live display | Incremental recognition or limited context | Partial/final event semantics and update logic |
| Role names are wrong | Unsupported mapping from generic speaker IDs | Trusted channel and session metadata |
Preserve source recording references and processing versions. Protect transcripts and derived summaries with appropriate access and retention. Generic speaker labels should not become a cross-call identity database by accident.
Release checklist
- Define whether the task requires diarization, role mapping or verified identity.
- Validate the exact audio format and API feature combination.
- Measure DER components with declared scoring settings.
- Review overlap and attribution-sensitive cases.
- Test streaming updates or batch completion and recovery.
- Keep uncertain statements reviewable before consequential use.
- Version changes and retain an operating owner.
For the surrounding pipeline, read real-time versus batch transcription. For generated summaries and tool behavior, use the LLM testing playbook.
Common questions
What is speaker diarization?
It assigns speaker labels to audio regions to describe who spoke when. The labels generally distinguish apparent participants within a recording; they are not proof of real-world identity.
What is diarization error rate?
DER combines missed speech, false-alarm speech and speaker-confusion time relative to reference speaker time. State the scoring settings, including overlap and boundary tolerance, when reporting it.
Can diarization handle overlapping speakers?
Some models represent overlap, but performance and output semantics vary. Test detection, word attribution and downstream behavior on overlapping examples from the target workload.
Does a speaker label identify the customer?
No. Use trusted session or channel evidence for role mapping and a separate approved process for identity verification. Diarization alone must not authorize business actions.
Is a low word error rate enough?
No. Word recognition can be good while speaker attribution is wrong. Evaluate both, especially when a summary or action depends on which participant made a statement.
Evaluate attribution before relying on it
For AI application choices, see RAG versus fine-tuning and prompt engineering. To review speech attribution and downstream reliability, discuss your production AI reliability roadmap.