
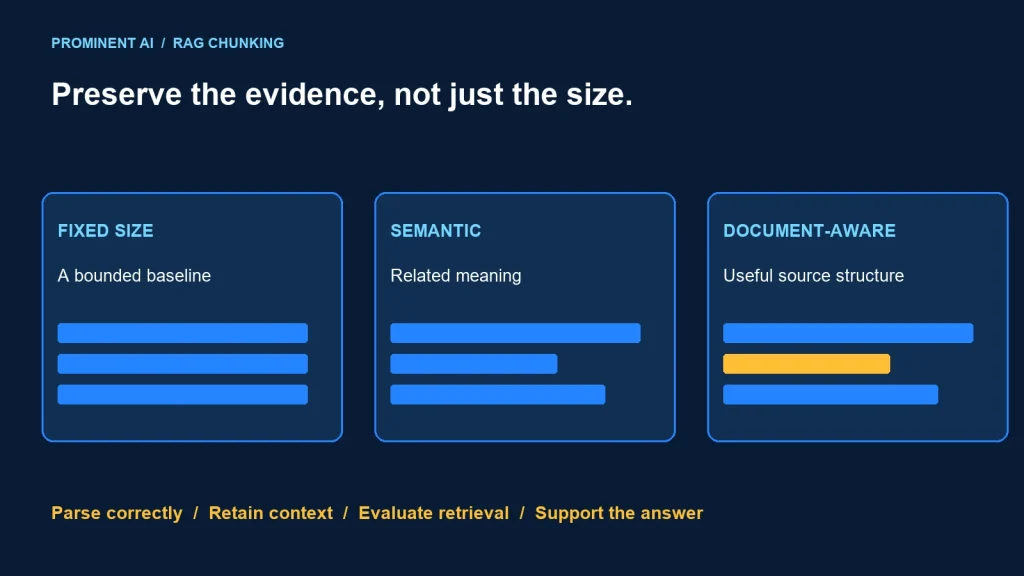
Choose a RAG chunking strategy that preserves the evidence needed to answer your users’ questions while fitting the embedding and generation pipeline’s limits. Fixed-size splitting offers a simple baseline. Semantic splitting tries to preserve related meaning. Document-aware splitting uses structural boundaries such as sections, table rows and code symbols. Many production pipelines combine these approaches.
There is no universal best chunk size. A short policy exception, a table and a source-code function have different context needs. This tutorial compares the strategies, provides a runnable boundary-regression demonstration and sets out an evaluation plan that separates parsing, retrieval and answer quality.
Start with evidence units, not an arbitrary number
- Inspect how real source documents are parsed before tuning chunk size.
- Preserve headings, qualifications, table headers and code relationships where they matter.
- Keep source references, version and access metadata with every chunk.
- Test fixed-size and structure-aware baselines before adding more complex splitting.
- Measure retrieval and supported answers on representative held-out questions.
Fixed size, semantic and document-aware splitting
Chunking breaks larger source content into retrievable units. It can help meet model input limits and prevent a broad document from being represented as one undifferentiated item. Microsoft’s chunking guide describes fixed-size, variable and semantic approaches. The appropriate configuration still depends on the corpus and questions.
| Strategy | Strength | Trade-off | Evaluate |
|---|---|---|---|
| Fixed size | Simple, predictable size bounds and a useful baseline | Can divide an evidence unit unless boundaries or overlap are handled | Size, overlap, tokenizer and boundary failures |
| Semantic | Attempts to group related meaning | Additional processing and configuration; coherence is not answer relevance | Topic shifts, long units, short exceptions and retrieval quality |
| Document-aware | Uses headings, rows, paragraphs or code structure | Depends on reliable parsing and may produce uneven sizes | Parser quality, oversized units and retained context |
| Combined | Preserves structure while applying size constraints | More ingestion rules to version and test | Fallback behavior and end-to-end evidence quality |
Words, characters and tokens are not interchangeable
A word-count demonstration is convenient to read, but production limits should be checked with the tokenizer or supported counting mechanism used by the actual model pipeline. Character counts and token counts can differ, especially across languages, symbols and code. Reserve room for metadata, instructions and other retrieved evidence as well as the chunk text.
Preserve context across source formats
Policies
Keep a rule connected to its exceptions, effective date and relevant heading. Splitting “allowed” from “only with approval” can change the apparent meaning. A policy chapter may need smaller units, but each unit should retain enough context to avoid presenting a qualification as an unrelated fragment.
Tables
A cell value often needs its row identifier, column header and units. Extracting the value alone can produce misleading evidence. Consider a representation that repeats required headers or associates a row with its parent table. Test merged cells, footnotes and multi-page tables explicitly.
PDFs
Parsing precedes chunking. Reading order, repeated headers, columns and OCR errors can damage the text before any splitter runs. Review extracted samples from actual source types. Do not expect a semantic splitter to repair a table whose columns were interleaved incorrectly.
Code
Functions, classes, signatures and nearby documentation can form useful units. Large symbols still need bounds, while small functions may require module context. Preserve language, path and symbol references so the answer can point to the right code version.
A runnable boundary-regression demonstration
The following standard-library Python code uses four fictional text fixtures: a policy sentence, flattened table text, a code note and PDF-like extracted text. These fixtures were deliberately selected to cross a 12-word boundary. They are not a representative benchmark and no PDF parser or semantic embedding model is used.
The test asks a narrow question: does a required phrase remain together inside at least one chunk? It compares a naive 12-word splitter without overlap against retaining each short fixture as one document unit. This shows a failure mode to test, not that all fixed-size splitting performs poorly.
import json

FIXTURES = [
    ('policy', 'Employees may carry forward five unused leave days only with manager approval before the annual cutoff.', 'manager approval before the annual cutoff'),
    ('table row text', 'Plan Standard includes monthly exports. Plan Premium includes daily exports and audit history.', 'daily exports and audit history'),
    ('code note', "def is_allowed(user): return user.active and user.has_scope('tickets:read') # deny access when the required scope is absent", 'required scope is absent'),
    ('PDF-like extracted text', 'Safety procedure step one isolate the device power supply before opening the service panel and record the isolation check.', 'before opening the service panel'),
]

def fixed_words(text, size=12):
    if size < 1:
        raise ValueError('size must be positive')
    words = text.split()
    return [' '.join(words[i:i + size]) for i in range(0, len(words), size)]

def phrase_preserved(chunks, phrase):
    return any(phrase in chunk for chunk in chunks)

if __name__ == '__main__':
    results = []
    for kind, text, phrase in FIXTURES:
        results.append({'fixture': kind,
                        'fixed_preserved': phrase_preserved(fixed_words(text), phrase),
                        'unit_preserved': phrase_preserved([text], phrase)})
    assert len(results) == 4
    assert all(r['unit_preserved'] for r in results)
    print(json.dumps(results, indent=2))
The local run returned fixed_preserved: false and unit_preserved: true for each of the four deliberately boundary-sensitive fixtures. Keeping each entire short fixture naturally preserves its phrase. These results are boundary checks, not retrieval recall, semantic coherence or generated-answer accuracy.
Turn the demonstration into a useful regression set
Add actual permitted document examples that have caused failures, including long sections and cases where a large unit adds irrelevant material. Test the production splitter, tokenizer and overlap configuration. Include examples where fixed-size splitting succeeds so the set does not reward one strategy by construction.
Evaluate parsing, retrieval and answers separately
For each representative question, label the source evidence needed for a supported answer. Keep those source references stable across chunking variants, because different splitters create different chunk IDs. Otherwise a relevance label attached only to one splitter’s chunk can distort the comparison.
- Parsing: inspect whether text, tables and relationships were extracted correctly.
- Boundary integrity: check whether the relevant rule or evidence unit remains understandable.
- Retrieval: measure how much required evidence reaches the candidate and final context sets.
- Answer support: judge whether the response follows the evidence and preserves qualifications.
- Operations: measure ingestion effort, index size, query latency and accounted cost.
Hold corpus version, permission scope, retrieval settings and questions constant while comparing chunking variants. Then test semantic splitting with a declared method and configuration. Do not infer semantic performance from the boundary demonstration above.
Evaluate overlap rather than maximizing it
Overlap can preserve context across boundaries while increasing duplication. Too much repeated material may consume retrieval slots and the context budget. Inspect whether the final context contains distinct evidence or several overlapping copies of the same paragraph.
For retrieval-method decisions, see hybrid, vector and keyword search for enterprise RAG.
A practical ingestion architecture
In the proposed pipeline, ingestion first parses and normalizes source content, then identifies structural units. A bounded splitter applies size constraints and any required overlap. Each resulting chunk carries the source reference, document version, structural path and access metadata before indexing.
Keep raw source, parsed representation and chunking configuration versioned enough to diagnose a retrieval failure. A source update may require retiring old chunks as well as creating new ones. Permission changes need a propagation path that prevents stale indexed content from reaching an unauthorized model request.
Use parent context selectively
A small matching chunk can identify a useful section, while permitted parent context supplies qualifications needed for the answer. Bound that expansion so retrieval does not turn every hit into an entire document. Reapply the appropriate source and access rules to any expanded material.
The surrounding architecture still needs source-aware answers and no-answer handling. See RAG architecture explained and RAG vs fine-tuning vs prompt engineering.
Deployment checklist
- Verify parsing samples for policies, tables, PDFs and code actually present in the corpus.
- Count inputs using the production model pipeline’s supported mechanism.
- Define handling for units that exceed size limits.
- Preserve headings, source references, version and permissions.
- Compare chunking variants on representative held-out questions.
- Test source updates, document removal and permission revocation.
- Record measured results without converting toy demonstrations into accuracy claims.
- Retain a versioned rollback path for the ingestion configuration.
Common questions about RAG chunking
What is the best chunking strategy for RAG?
Should every chunk have the same size?
Does semantic chunking fix PDF extraction errors?
Is more overlap always better?
What does the tutorial’s boundary test prove?
Choose chunks around your evidence
Request an enterprise RAG architecture review with Prominent AI Services LLP. Bring representative documents, questions and examples of missing or misleading evidence.
Technical reference reviewed 2 November 2026. The boundary demonstration was run locally with fictional fixtures; production quality requires corpus-specific evaluation.